Evals

A collection of 5 posts
Enter GovWork-Bench, our take on what an eval for Public Service work could look like.
The Lab

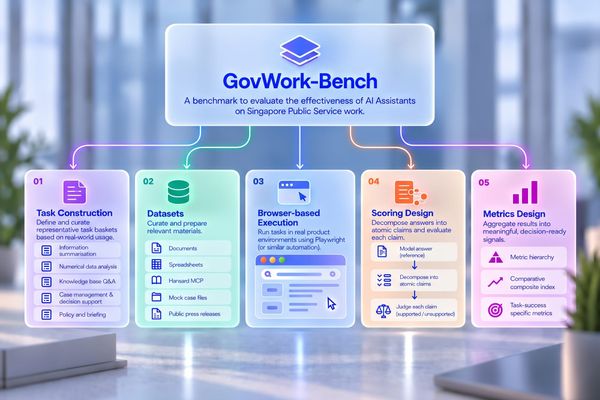
GovWork-Bench – A Singapore Public Service Benchmark to evaluate AI Assistants on Public Service tasks

Evals are all the rage in the AI space recently, especially with news of GPT-6 Astra saturating long-standing difficult benchmarks like ARC-AGI-3 and FrontierMath (Tier 4). In this article, we too are sharing our latest work on benchmarking — but with a unique Public Sector twist!
AgenticEvals
Behind VEILED Expressions: A Singapore-context benchmark for mental-health AI evaluation
The Studio

Behind VEILED Expressions: A Singapore-context benchmark for mental-health AI evaluation

We built VEILED-SH to evaluate indirect self-harm/suicide language in the Singapore context, shaped by local language, privacy safeguards and practitioner insight.
Responsible AIEvals
Building a Smart and Safe Whole-of-Government Chatbot for Singaporeans
The Studio

Building a Smart and Safe Whole-of-Government Chatbot for Singaporeans

How we build custom policy guardrails and balance safety with helpfulness for chat.gov.sg
Responsible AIEvals
MetaEvaluator: Systematically Evaluate Your LLM Judges
The Lab

MetaEvaluator: Systematically Evaluate Your LLM Judges

Measure how well your app is performing and more importantly where it's failing.
Evals
Benchmarking GPT-5 & GPT-OSS: A Responsible AI Approach
The Lab

Benchmarking GPT-5 & GPT-OSS: A Responsible AI Approach

Evaluating dimensions often overlooked by traditional benchmarks.
Responsible AIEvals